
2. Downloading and organizing files
Last updated on 2026-11-10 | Edit this page
Estimated time: 35 minutes
Overview
Questions
- What files are required to process raw RNA seq reads?
- Where do we obtain raw reads, reference genomes, annotations, and transcript sequences?
- How should project directories be organized to support a smooth workflow?
- What practical considerations matter when downloading and preparing RNA seq data?
Objectives
- Identify the essential inputs for RNA seq analysis: FASTQ files, reference genome, annotation, and transcript sequences.
- Learn where and how to download RNA seq datasets and reference materials.
- Create a clean project directory structure suitable for quality control, alignment, and quantification.
- Understand practical issues such as compressed FASTQ files and adapter trimming.
Introduction
Before we can perform quality control, mapping, or quantification, we must first gather the files required for RNA seq analysis and organize them in a reproducible way. This episode introduces the essential inputs of an RNA seq workflow and demonstrates how to obtain and structure them on a computing system.
We begin by discussing raw FASTQ reads, reference genomes, annotation files, and transcript sequences. We then download the dataset used throughout the workshop and set up the directory structure that supports downstream steps.
Most FASTQ files arrive compressed as .fastq.gz files.
Modern RNA seq tools accept compressed files directly, so uncompressing
them is usually unnecessary.
Should I uncompress FASTQ files?
In almost all RNA-seq workflows, you should keep FASTQ files
compressed. Tools such as FastQC, HISAT2, STAR, Salmon, and fastp can
read .gz files directly. Keeping files compressed saves
space and reduces input and output overhead.
Many library preparation protocols introduce adapter sequences at the ends of reads. For most alignment based analyses, explicit trimming is not required because aligners soft clip adapter sequences automatically.
Should I trim adapters for RNA seq analysis?
In most cases, no. Aligners such as HISAT2 and STAR soft clip adapter
sequences. Overly aggressive trimming can reduce mapping rates or
distort read length distributions. Trimming is needed only for specific
applications such as transcript assembly where uniform read lengths are
important.
More information: https://pmc.ncbi.nlm.nih.gov/articles/PMC4766705/
The workshop dataset: p53-mediated response to ionizing radiation
For this workshop, we use a subset of a publicly available dataset (GEO accession GSE71176) that investigates the transcriptional response to ionizing radiation (IR) in mouse B cells. The original study by Tonelli et al. (2015) examined how the tumor suppressor p53 (encoded by Trp53) regulates gene expression following DNA damage.
Biological context
The TP53 gene (called Trp53 in mice) encodes the p53 protein, often called the “guardian of the genome.” When cells experience DNA damage, such as double-strand breaks caused by ionizing radiation, p53 activates transcriptional programs that lead to:
- Cell cycle arrest (allowing time for DNA repair)
- Apoptosis (programmed cell death if damage is irreparable)
- Senescence (permanent growth arrest)
- Metabolic reprogramming
Mutations in TP53 are among the most common alterations in human cancers, occurring in approximately 50% of all tumors. Understanding p53-regulated genes is therefore central to cancer biology.
Experimental design
The full dataset includes wild-type (WT) and p53-knockout (KO) mouse B cells, with and without IR treatment (7 Gy, 4 hours post-exposure). For simplicity, we will focus on 8 samples from wild-type B cells only:
| Condition | Description | Samples | Replicates |
|---|---|---|---|
| WT_mock (control) | Wild-type B cells, no radiation | 4 | SRR2121778-81 |
| WT_IR (treatment) | Wild-type B cells, 4h post 7Gy IR | 4 | SRR2121786-89 |
This balanced design (n=4 per group) allows us to identify genes that respond to ionizing radiation in cells with functional p53.
The full GSE71176 series has 24 samples
GSE71176 (SRA study SRP061386; Illumina HiSeq 2000, paired-end reads) profiles splenic B cells and splenic non-B cells from wild-type (Trp53+/+) and p53-knockout (Trp53-/-) mice, mock-treated or 4 hours after 7 Gy whole-body irradiation:
| Genotype | Cell type | Mock | IR (7 Gy, 4 h) |
|---|---|---|---|
| Wild type | B cells | 4 (used here) | 4 (used here) |
| Wild type | non-B cells | 4 | 4 |
| Trp53-/- | B cells | 2 | 2 |
| Trp53-/- | non-B cells | 2 | 2 |
The workshop uses only the 8 wild-type B-cell samples. A single
two-group comparison with 4 replicates per group is the simplest design
that teaches the whole workflow, and the IR response in wild-type cells
gives clear positive controls. The knockout groups have only 2
replicates each, and bringing in genotype or cell type would need a
multi-factor design (for example
~ genotype + treatment + genotype:treatment to ask whether
the IR response depends on p53). Those samples make a good exercise
after the workshop.
Pick the workshop samples from the full series
The table below lists all 24 runs of SRP061386 (GEO sample characteristics and SRA run information, retrieved 2026-10-02). Which 8 runs make up the workshop dataset, and which of them are the controls?
| Run | GEO sample | Genotype | Cell type | Treatment | Read pairs (millions) |
|---|---|---|---|---|---|
| SRR2121770 | GSM1828861 | Trp53-/- | B cells | mock | 118 |
| SRR2121771 | GSM1828862 | Trp53-/- | B cells | mock | 103 |
| SRR2121772 | GSM1828863 | Trp53-/- | non-B cells | mock | 131 |
| SRR2121773 | GSM1828864 | Trp53-/- | non-B cells | mock | 128 |
| SRR2121774 | GSM1828865 | Trp53-/- | B cells | 7 Gy IR, 4 h | 91 |
| SRR2121775 | GSM1828866 | Trp53-/- | B cells | 7 Gy IR, 4 h | 109 |
| SRR2121776 | GSM1828867 | Trp53-/- | non-B cells | 7 Gy IR, 4 h | 110 |
| SRR2121777 | GSM1828868 | Trp53-/- | non-B cells | 7 Gy IR, 4 h | 76 |
| SRR2121778 | GSM1828869 | Trp53+/+ | B cells | mock | 137 |
| SRR2121779 | GSM1828870 | Trp53+/+ | B cells | mock | 124 |
| SRR2121780 | GSM1828871 | Trp53+/+ | B cells | mock | 100 |
| SRR2121781 | GSM1828872 | Trp53+/+ | B cells | mock | 106 |
| SRR2121782 | GSM1828873 | Trp53+/+ | non-B cells | mock | 103 |
| SRR2121783 | GSM1828874 | Trp53+/+ | non-B cells | mock | 109 |
| SRR2121784 | GSM1828875 | Trp53+/+ | non-B cells | mock | 98 |
| SRR2121785 | GSM1828876 | Trp53+/+ | non-B cells | mock | 105 |
| SRR2121786 | GSM1828877 | Trp53+/+ | B cells | 7 Gy IR, 4 h | 100 |
| SRR2121787 | GSM1828878 | Trp53+/+ | B cells | 7 Gy IR, 4 h | 75 |
| SRR2121788 | GSM1828879 | Trp53+/+ | B cells | 7 Gy IR, 4 h | 83 |
| SRR2121789 | GSM1828880 | Trp53+/+ | B cells | 7 Gy IR, 4 h | 92 |
| SRR2121790 | GSM1828881 | Trp53+/+ | non-B cells | 7 Gy IR, 4 h | 80 |
| SRR2121791 | GSM1828882 | Trp53+/+ | non-B cells | 7 Gy IR, 4 h | 83 |
| SRR2121792 | GSM1828883 | Trp53+/+ | non-B cells | 7 Gy IR, 4 h | 94 |
| SRR2121793 | GSM1828884 | Trp53+/+ | non-B cells | 7 Gy IR, 4 h | 157 |
The wild-type B-cell runs: SRR2121778 to SRR2121781 are the mock controls (WT_Bcell_mock_rep1 to rep4) and SRR2121786 to SRR2121789 are the irradiated samples (WT_Bcell_IR_rep1 to rep4). In the SRA Run Selector you would filter on genotype and cell type, then download the accession list for just these 8 runs.
Expected biological results
Because p53 is a transcription factor activated by DNA damage, we expect to see upregulation of canonical p53 target genes in IR-treated samples:
Genes expected to be upregulated (IR vs mock):
- Cdkn1a (p21) - cell cycle arrest
- Bax, Bbc3 (Puma), Pmaip1 (Noxa) - pro-apoptotic
- Mdm2 - negative feedback regulator of p53
- Gadd45a - DNA damage response (in the subsampled workshop data only a small increase that is not statistically significant)
- Fas, Tnfrsf10b (DR5) - death receptor signaling
Pathways expected to be enriched (all among genes that go up after IR, on both analysis tracks):
- p53 signaling: the KEGG p53 signaling pathway and the MSigDB Hallmark p53 pathway (Episode 6, over-representation analysis)
- DNA damage response: GO terms for DNA damage signal transduction by p53 (over-representation of upregulated genes and GSEA)
- Apoptosis: GO intrinsic apoptotic signaling in response to DNA damage (GSEA)
- Cell cycle: GO DNA damage and mitotic cell cycle checkpoint signaling (GSEA)
At 20 million read pairs, the broader Hallmark apoptosis and cell cycle (G2M, E2F) sets do not reach significance; the more specific GO terms do.
The presence of these expected results serves as a positive control that our analysis pipeline is working correctly.
Why this dataset?
This dataset is ideal for teaching because:
- Simple two-group comparison: Control vs. treatment with balanced replicates
- Clear biological interpretation: DNA damage response is well-characterized
- Expected positive controls: Known p53 targets should appear as top hits
- Clinical relevance: p53 biology is fundamental to cancer research
- Model organism: Mouse with excellent genome annotation
Project organization
Before downloading files, we create a reproducible directory layout for raw data, scripts, mapping outputs, and count files.
Create the directories needed for this episode
Create a working directory for the workshop (e.g.,
rnaseq-workshop). Inside it, create three
subdirectories:
-
data: raw FASTQ files, reference genome, annotation -
scripts: custom scripts, SLURM job files -
results: alignment, counts and various other outputs
What files do I need for RNA-seq analysis?
You will need:
- Raw reads (FASTQ)
- Usually
.fastq.gzfiles containing nucleotide sequences and per-base quality scores.
- Usually
For alignment based workflows
- Reference genome (FASTA)
- Contains chromosome or contig sequences.
- Annotation file (GTF/GFF)
- Describes gene models: exons, transcripts, coordinates.
For transcript-level quantification workflows
- Transcript sequences (FASTA)
- Required for transcript-based quantification with tools such as Salmon, Kallisto, and RSEM.
Reference files must be consistent with each other (same genome version). To ensure a smooth analysis workflow, keep these files logically organized. Good directory structure minimizes mistakes, simplifies scripting, and supports reproducibility.
Downloading the data
We now download:
- the GRCm39 reference genome
- the corresponding GENCODE annotation
- transcript sequences (if using transcript based quantification)
- raw FASTQ files from SRA
Reference genome and annotation
We will use GENCODE GRCm39 (M38) as the reference.
Annotation
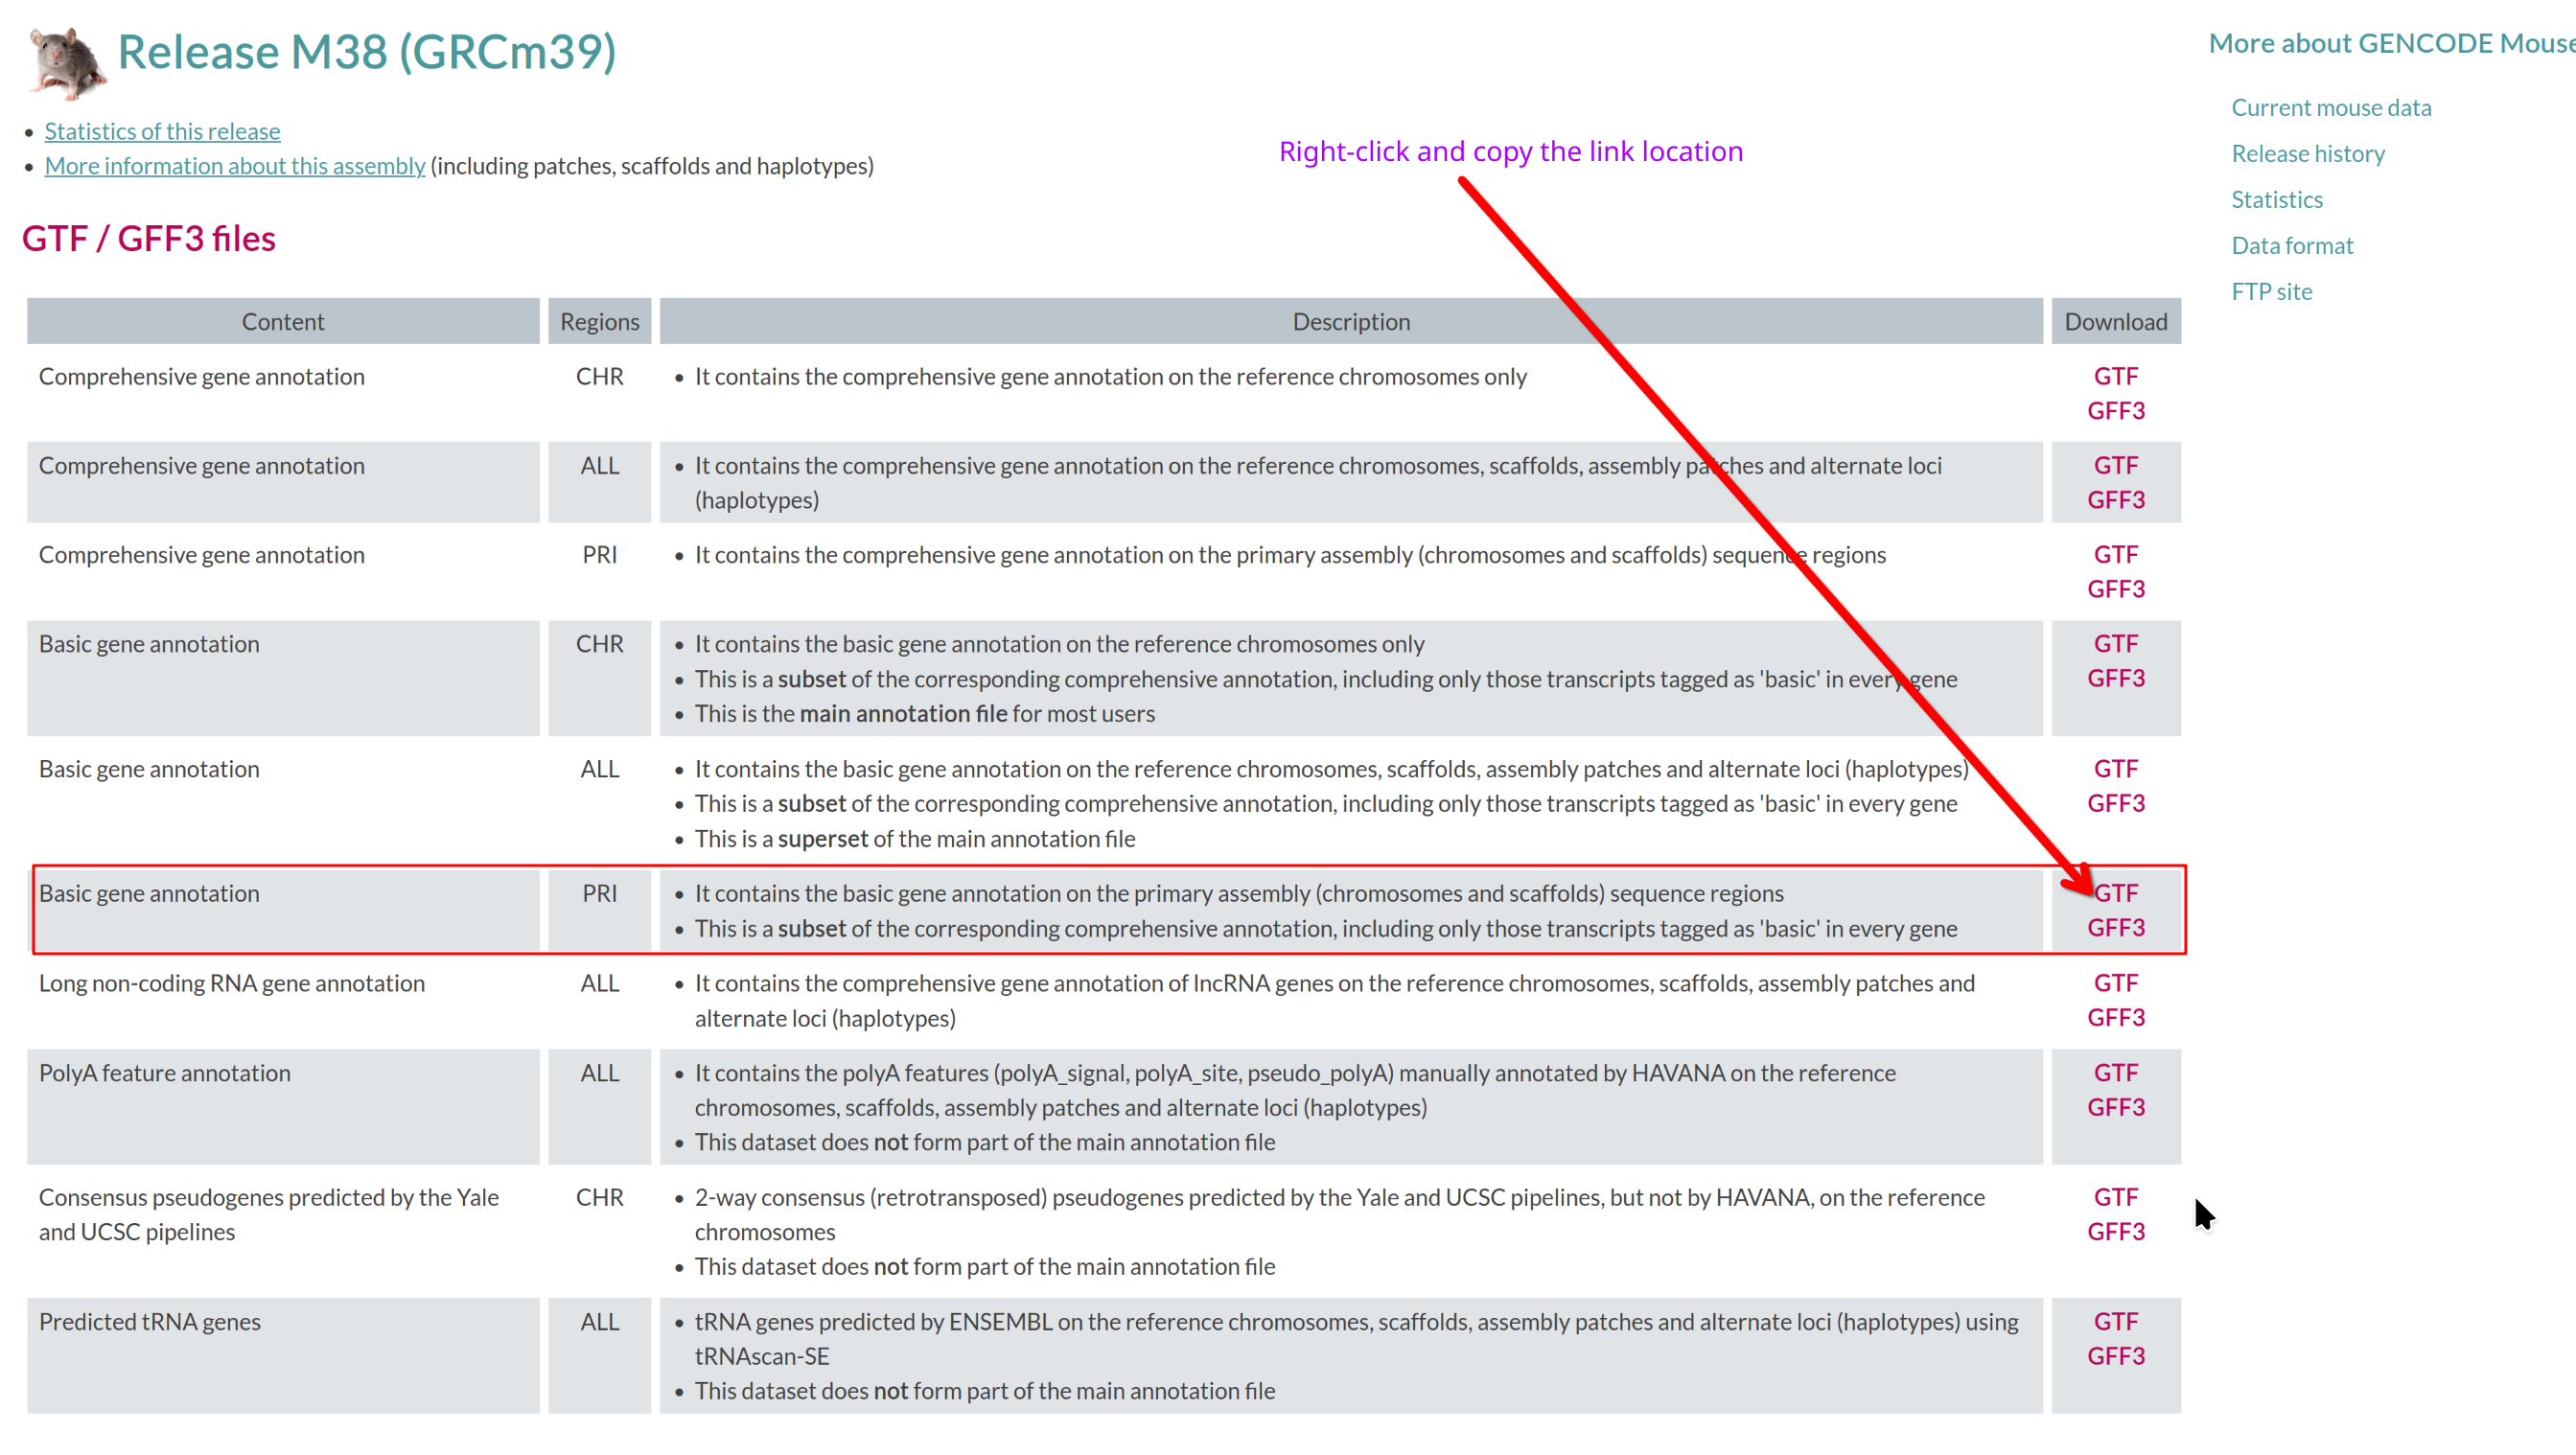
Visit the GENCODE mouse page: https://www.gencodegenes.org/mouse/.
Which annotation file (GTF/GFF3 files section) should you download, and
why?
Use the basic gene annotation in GTF format (e.g.,
gencode.vM38.primary_assembly.basic.annotation.gtf.gz).
It contains essential gene and transcript models without pseudogenes or
other biotypes not typically used for RNA-seq quantification.
Reference genome
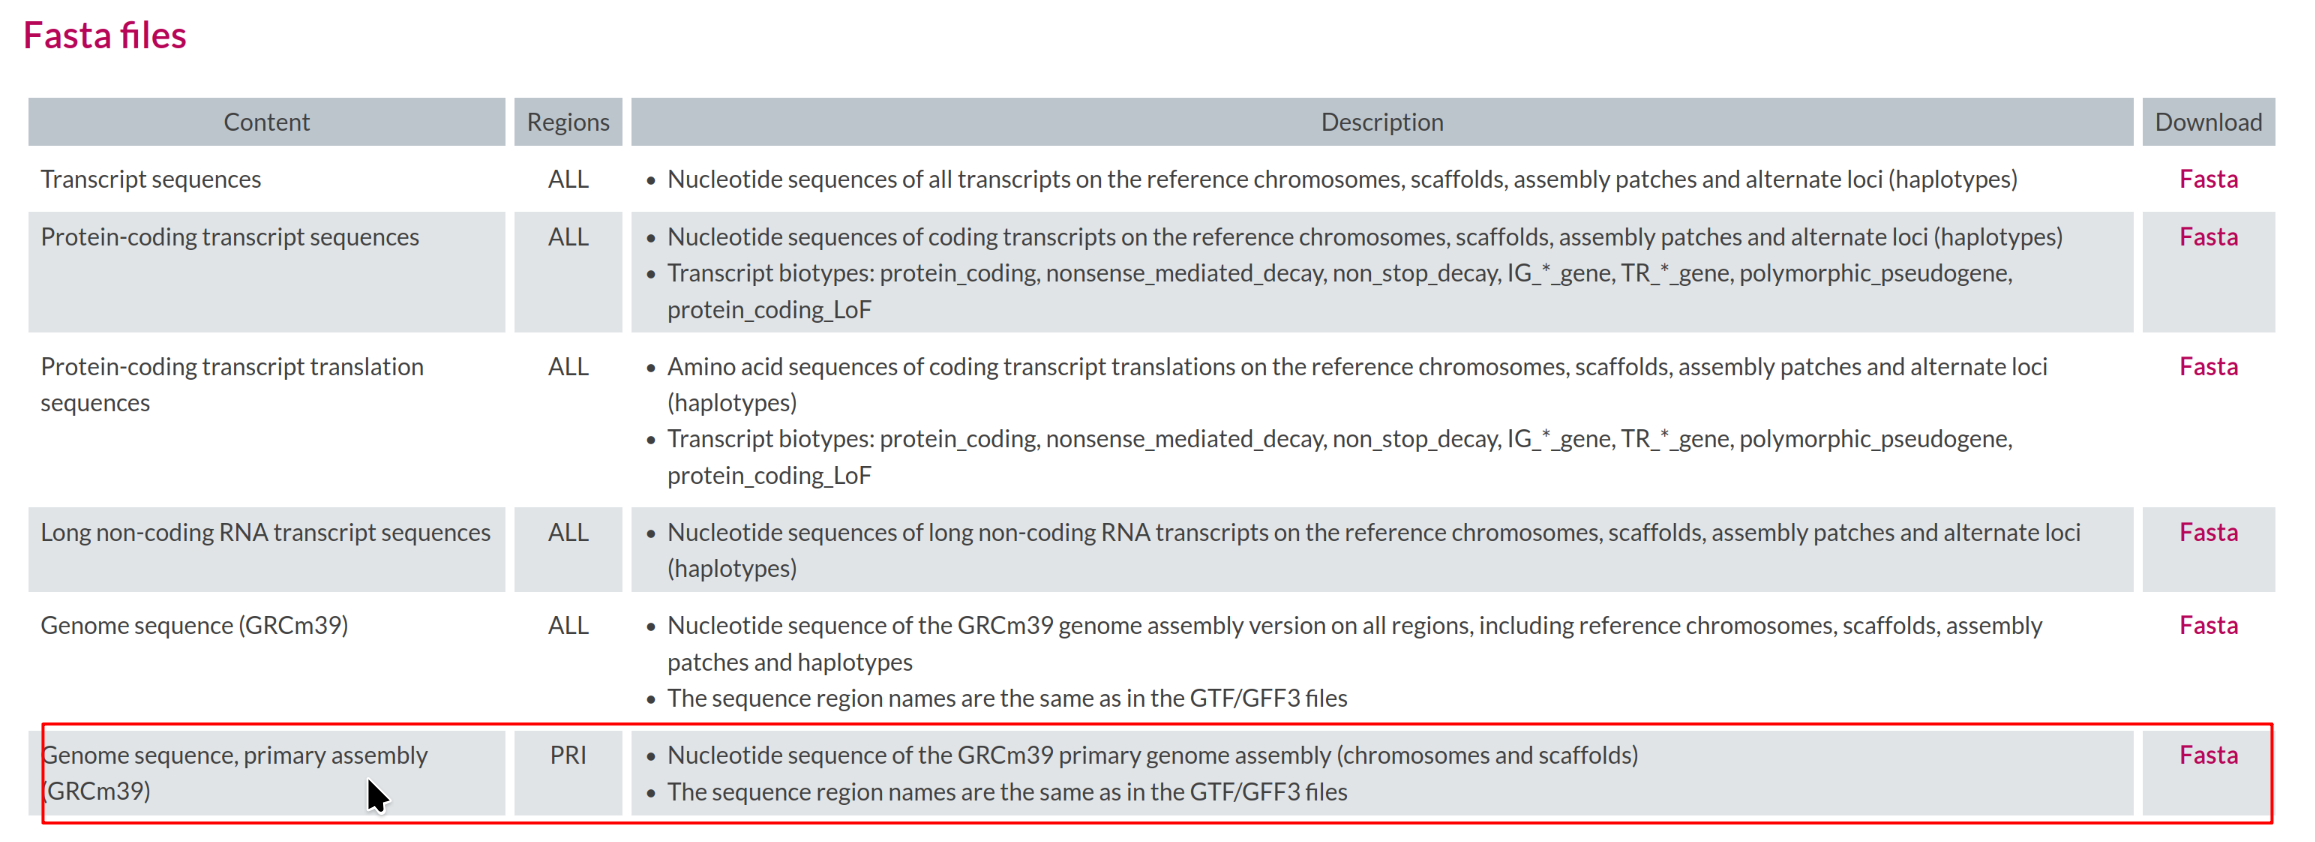
Select the corresponding Genome sequence (GRCm39)
FASTA (e.g.,
GRCm39.primary_assembly.genome.fa.gz).
Transcript sequences
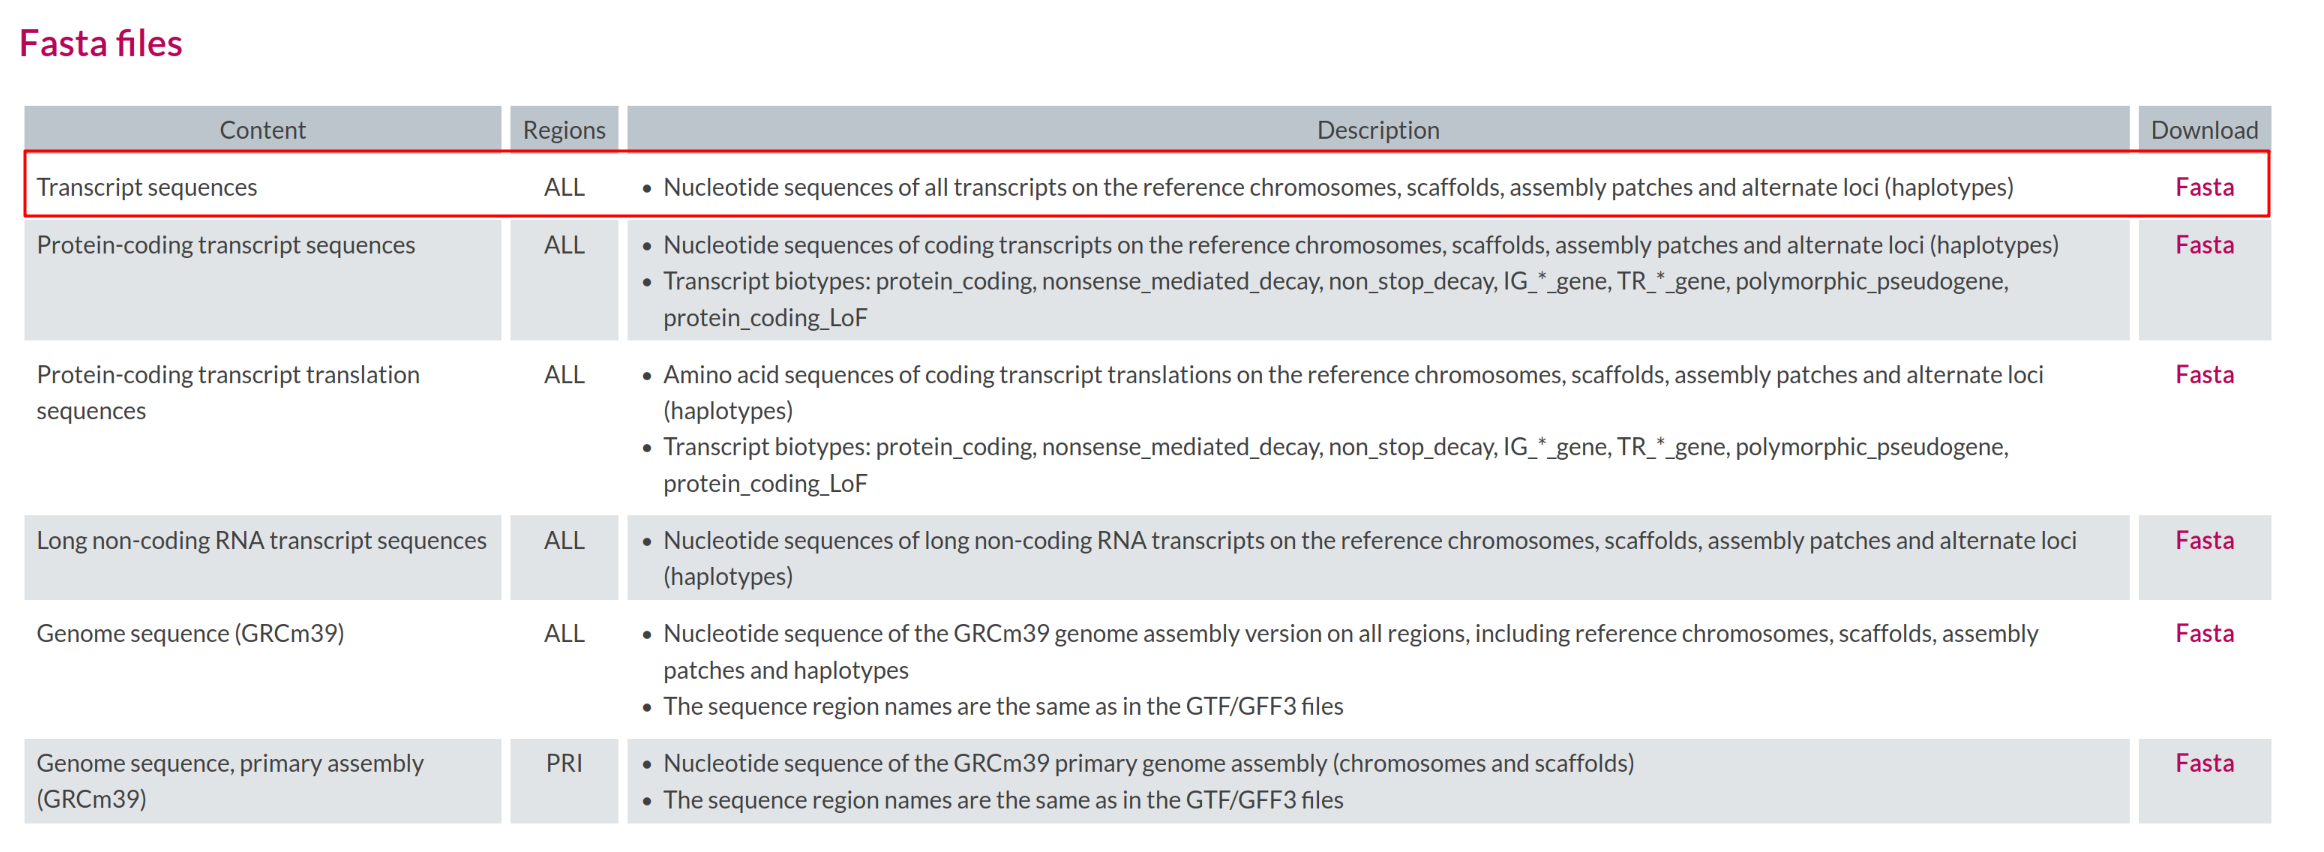
Transcript level quantification requires a transcript FASTA file
consistent with the annotation. GENCODE provides transcript sequences
for all transcripts in GRCm39
(gencode.vM38.transcripts.fa.gz).
Transcript sequence file
Where on the GENCODE page can you find the transcript FASTA file?
The transcript FASTA file is available in the same release directory
as the genome and annotation files (under FASTA files). It is named
gencode.vM38.transcripts.fa.gz.
Downloading all reference files
Already done if you copied the workshop data
The workshop copy you made in Setup already contains these reference
files, uncompressed, in data/. If you run this block in
that directory, gunzip stops with “already exists; not
overwritten” because the .fa and .gtf files
are present. Read the commands here; run them only when you set up a
project from scratch.
BASH
cd ${SCRATCH}/rnaseq-workshop

GTFlink="https://ftp.ebi.ac.uk/pub/databases/gencode/Gencode_mouse/release_M38/gencode.vM38.primary_assembly.basic.annotation.gtf.gz"
GENOMElink="https://ftp.ebi.ac.uk/pub/databases/gencode/Gencode_mouse/release_M38/GRCm39.primary_assembly.genome.fa.gz"
CDSLink="https://ftp.ebi.ac.uk/pub/databases/gencode/Gencode_mouse/release_M38/gencode.vM38.transcripts.fa.gz"

# Download to 'data'
wget -P data ${GENOMElink}
wget -P data ${GTFlink}
wget -P data ${CDSLink}

# Uncompress
cd data
gunzip GRCm39.primary_assembly.genome.fa.gz
gunzip gencode.vM38.primary_assembly.basic.annotation.gtf.gz
gunzip gencode.vM38.transcripts.fa.gz
The transcript file header has multiple pieces of information which often interfere with downstream analysis. We create a simplified version containing only the transcript IDs.
Raw reads
-
Study: Genome-wide analysis of p53 transcriptional
programs in B cells upon exposure to genotoxic stress in
vivo
- Organism: Mus musculus (C57BL/6)
- Cell type: Primary B cells from spleen
- Design: Wild-type mock vs Wild-type IR-treated (n=4 per group)
- Treatment: 7 Gy ionizing radiation, harvested 4 hours post-exposure
- Sequencing: Illumina HiSeq 2000, paired-end 51bp
- GEO: GSE71176
- Reference: Tonelli et al. Oncotarget 2015 Sep 22;6(28):24611-26. PMID: 26372730
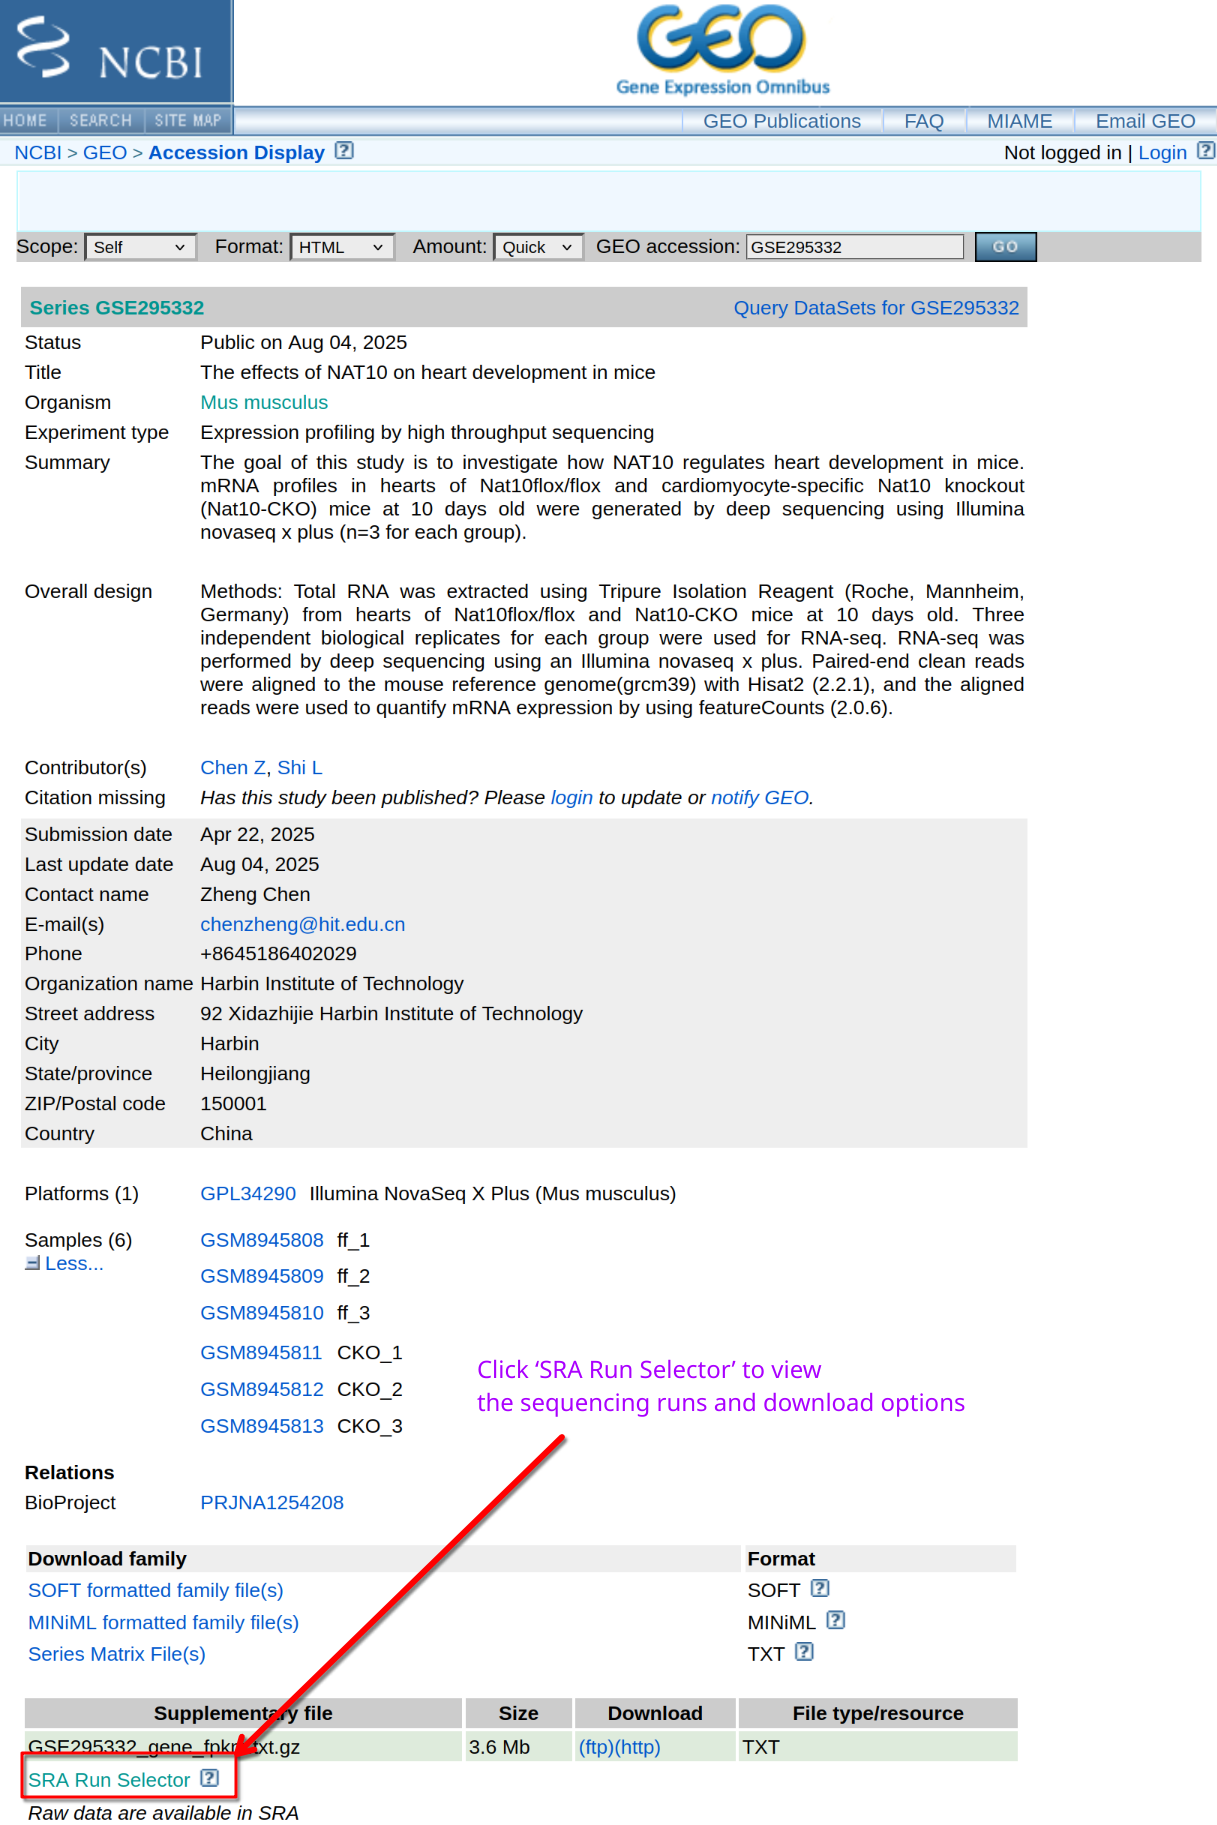
Where do you find FASTQ files?
GEO provides metadata and experimental details, but FASTQ files are stored in the SRA. How do you obtain the complete list of sequencing runs?
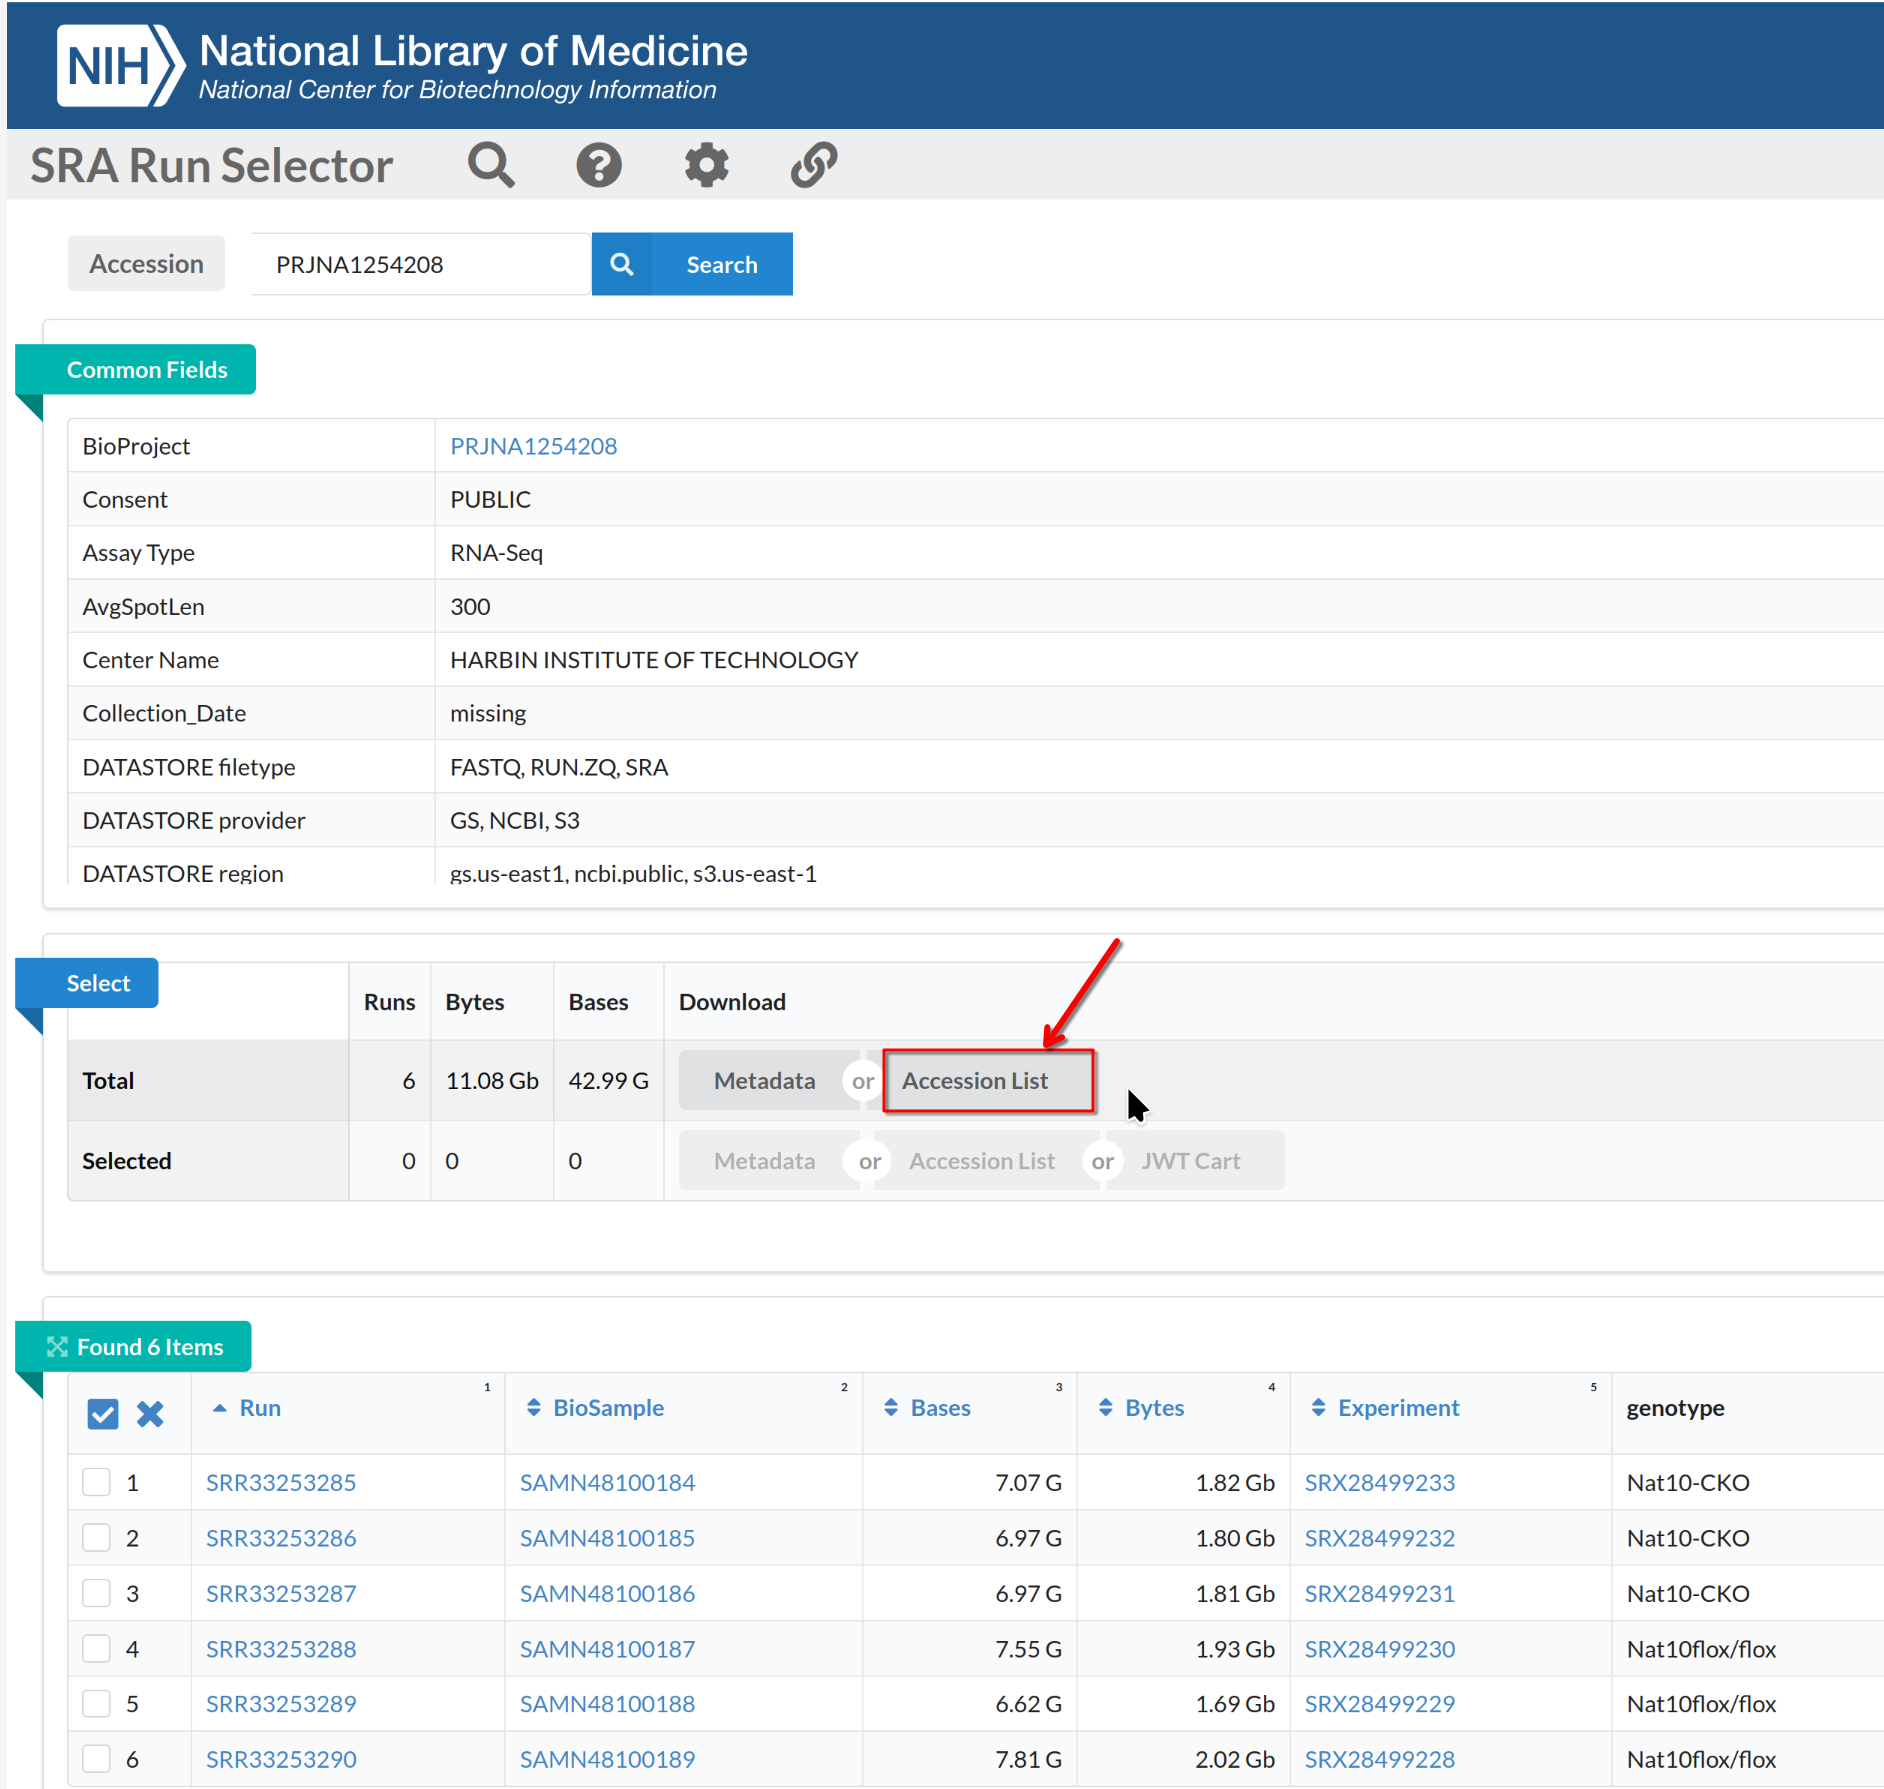
Navigate to the SRA page for the BioProject and use Run
Selector to list runs.
On the Run Selector page, select the accessions (SRR2121778-81,
SRR2121786-89), toggle the “selected” and click Accession
List to download the selected SRR accession IDs.
Download FASTQ files with SRA Toolkit
[DO NOT RUN THIS COMMAND DURING THE WORKSHOP - IT TAKES TOO LONG TO COMPLETE]. You already copied the pre-downloaded data to your scratch space.
BASH
sinteractive -A rcac-rnaseq -q standby -p cpu -N 1 -n 4 --time=1:00:00
cd ${SCRATCH}/rnaseq-workshop/data
module load biocontainers
module load sra-tools
while read SRR; do
   fasterq-dump --threads 4 --progress $SRR;
   gzip ${SRR}_1.fastq
   gzip ${SRR}_2.fastq
done<SRR_Acc_List.txt
# rename files to meaningful names
# WT B cells - mock
mv SRR2121778_1.fastq.gz WT_Bcell_mock_rep1_R1.fastq.gz
mv SRR2121778_2.fastq.gz WT_Bcell_mock_rep1_R2.fastq.gz
mv SRR2121779_1.fastq.gz WT_Bcell_mock_rep2_R1.fastq.gz
mv SRR2121779_2.fastq.gz WT_Bcell_mock_rep2_R2.fastq.gz
mv SRR2121780_1.fastq.gz WT_Bcell_mock_rep3_R1.fastq.gz
mv SRR2121780_2.fastq.gz WT_Bcell_mock_rep3_R2.fastq.gz
mv SRR2121781_1.fastq.gz WT_Bcell_mock_rep4_R1.fastq.gz
mv SRR2121781_2.fastq.gz WT_Bcell_mock_rep4_R2.fastq.gz
# WT B cells - IR
mv SRR2121786_1.fastq.gz WT_Bcell_IR_rep1_R1.fastq.gz
mv SRR2121786_2.fastq.gz WT_Bcell_IR_rep1_R2.fastq.gz
mv SRR2121787_1.fastq.gz WT_Bcell_IR_rep2_R1.fastq.gz
mv SRR2121787_2.fastq.gz WT_Bcell_IR_rep2_R2.fastq.gz
mv SRR2121788_1.fastq.gz WT_Bcell_IR_rep3_R1.fastq.gz
mv SRR2121788_2.fastq.gz WT_Bcell_IR_rep3_R2.fastq.gz
mv SRR2121789_1.fastq.gz WT_Bcell_IR_rep4_R1.fastq.gz
mv SRR2121789_2.fastq.gz WT_Bcell_IR_rep4_R2.fastq.gzWorkshop data is subsampled
The FASTQ files provided for this workshop have been subsampled to 20 million read pairs per sample. The original samples contain 75 to 137 million read pairs each, and running the full pipeline would take many hours—far exceeding our workshop session time.
Never subsample your real experimental data. This is done exclusively for workshop time constraints. Subsampling reduces statistical power and may affect differential expression results.
For reference, here is how the workshop data was prepared. You do not need to run this—the pre-downloaded data is already subsampled.
The original samples from SRA contain 75 to 137 million read pairs
each (SRA run info for SRR2121778-81 and SRR2121786-89). To enable
completion of the full analysis pipeline within a single workshop day,
we subsample to 20 million read pairs per sample using
seqtk.
BASH
# Subsample reads to 20 million per sample (WORKSHOP ONLY - do not do this with real data!)
module load biocontainers
module load seqtk

mkdir -p subsampled
for sample in WT_Bcell_mock_rep1 WT_Bcell_mock_rep2 WT_Bcell_mock_rep3 WT_Bcell_mock_rep4 \
              WT_Bcell_IR_rep1 WT_Bcell_IR_rep2 WT_Bcell_IR_rep3 WT_Bcell_IR_rep4; do
    # Use same seed for R1 and R2 to maintain pairing
    seqtk sample -s 42 ${sample}_R1.fastq.gz 20000000 | gzip > subsampled/${sample}_R1.fastq.gz
    seqtk sample -s 42 ${sample}_R2.fastq.gz 20000000 | gzip > subsampled/${sample}_R2.fastq.gz
done

# Archive original files, then move the subsampled files into place
mkdir -p original_reads
mv *_R1.fastq.gz *_R2.fastq.gz original_reads/
mv subsampled/*.fastq.gz .
rmdir subsampled
Why 20 million reads?
- Sufficient depth for differential expression analysis of moderately expressed genes
- Keeps STAR alignment to 2 to 3 minutes per sample on 20 cores
- Allows completion of the full workshop pipeline in a single day
- Still produces biologically meaningful results for well-expressed p53 target genes
What you lose by subsampling:
- Statistical power to detect lowly expressed genes
- Precision in abundance estimates
- Ability to detect subtle fold changes
- Some lowly expressed transcripts may appear as zeros
For your own research, always use the full sequencing depth. Modern RNA-seq experiments typically aim for 20-50 million reads for differential expression, but the original unsubsampled data is always preferred.
The directory, after downloading, should look like this:
data
├── annot.tsv
├── gencode.vM38.primary_assembly.basic.annotation.gtf
├── gencode.vM38.transcripts-clean.fa
├── gencode.vM38.transcripts.fa
├── GRCm39.primary_assembly.genome.fa
├── mart.tsv
├── SRR_Acc_List.txt
├── tx2gene.tsv
├── WT_Bcell_IR_rep1_R1.fastq.gz
├── WT_Bcell_IR_rep1_R2.fastq.gz
├── WT_Bcell_IR_rep2_R1.fastq.gz
├── WT_Bcell_IR_rep2_R2.fastq.gz
├── WT_Bcell_IR_rep3_R1.fastq.gz
├── WT_Bcell_IR_rep3_R2.fastq.gz
├── WT_Bcell_IR_rep4_R1.fastq.gz
├── WT_Bcell_IR_rep4_R2.fastq.gz
├── WT_Bcell_mock_rep1_R1.fastq.gz
├── WT_Bcell_mock_rep1_R2.fastq.gz
├── WT_Bcell_mock_rep2_R1.fastq.gz
├── WT_Bcell_mock_rep2_R2.fastq.gz
├── WT_Bcell_mock_rep3_R1.fastq.gz
├── WT_Bcell_mock_rep3_R2.fastq.gz
├── WT_Bcell_mock_rep4_R1.fastq.gz
└── WT_Bcell_mock_rep4_R2.fastq.gz

0 directories, 24 files- RNA-seq requires three main inputs: FASTQ reads, a reference genome (FASTA), and gene annotation (GTF/GFF).
- In lieu of a reference genome and annotation, transcript sequences (FASTA) can be used for transcript-level quantification.
- Keeping files compressed and well-organized supports reproducible analysis.
- Reference files must match in genome build and version.
- Public data repositories such as GEO and SRA provide raw reads and metadata.
- Tools like
wgetandfasterq-dumpenable programmatic, reproducible data retrieval.